Key Concepts
Logistic Regression, Binary Classification, Probability, Linear Regression, Sigmoid Function, Logit, Parameters (Theta), Bias/Intercept, Likelihood Function, Log Likelihood, Cross-Entropy Loss Function, Gradient Descent, Partial Derivatives, Chain Rule, Learning Rate, Matrix/Vector Notation.
1. Theoretical Foundations of Logistic Regression
- Logistic Regression as Classification: Despite the name, logistic regression is a classification algorithm used to predict the probability of a binary outcome (0 or 1).
- Probability Output: Instead of directly outputting a class label, it outputs a probability between 0 and 1, representing the likelihood of the instance belonging to class 1.
- Example: An image classified as a cat with a probability of 0.768 means there's a 76.8% chance it's a cat.
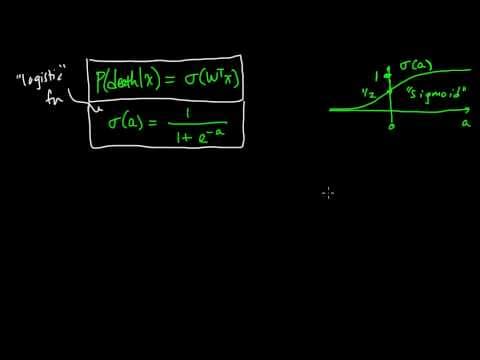
- Linear Regression with Sigmoid: Logistic regression combines linear regression with a sigmoid function to constrain the output between 0 and 1.
- Input features (xᵢ) are multiplied by parameters (θ) to produce a logit (zᵢ).
- The logit is then passed through the sigmoid function to obtain the predicted probability (h(xᵢ)).
- Logit Calculation: zᵢ = θᵀ * xᵢ, where θ is the parameter vector and xᵢ is the feature vector for the i-th instance.
- Sigmoid Function: σ(z) = 1 / (1 + e⁻ᶻ). This function maps any real-valued number to a value between 0 and 1.
- Bias Term: A bias or intercept term is added to the linear combination to allow the decision boundary to shift, improving model flexibility. This is implemented by adding a '1' as the first element of the feature vector.
2. Deriving the Cross-Entropy Loss Function
- Need for Optimization: The raw probability output from the sigmoid function cannot be directly optimized. A loss function is needed to quantify the error between predicted probabilities and actual labels.
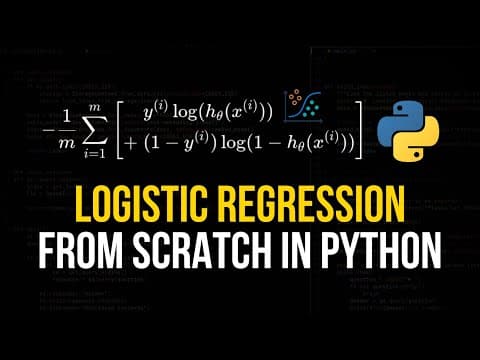
- Likelihood Function: The likelihood function measures how well the parameters fit the data. It's the product of probabilities of observing the actual outcomes given the predicted probabilities.
- L(θ) = ∏ᵢ [h(xᵢ) ]^yᵢ * [1 - h(xᵢ)]^(1 - yᵢ), where yᵢ is the true label (0 or 1).
- Log Likelihood: The logarithm of the likelihood function is used for numerical stability and to simplify calculations. The product turns into a sum.
- ln(L(θ)) = ∑ᵢ [yᵢ * ln(h(xᵢ)) + (1 - yᵢ) * ln(1 - h(xᵢ))].
- Cross-Entropy Loss: The cross-entropy loss function is the negative average log likelihood. It's the function that is minimized during training.
- J(θ) = -1/m * ∑ᵢ [yᵢ * ln(h(xᵢ)) + (1 - yᵢ) * ln(1 - h(xᵢ))], where m is the number of instances.
- Minimization: The goal is to find the parameters (θ) that minimize the cross-entropy loss.
3. Gradient Descent and Parameter Optimization
- Gradient Descent: An iterative optimization algorithm used to find the minimum of the loss function. It updates the parameters in the opposite direction of the gradient.
- Partial Derivatives: Partial derivatives are used to determine how each parameter affects the loss function.
- ∂J/∂θⱼ represents the change in the loss function with respect to a small change in parameter θⱼ.
- Chain Rule: The chain rule is used to calculate the partial derivatives of the loss function with respect to the parameters. It breaks down the derivative into smaller, manageable parts.
- Derivative Calculation: The video details the derivation of the partial derivative of the cross-entropy loss with respect to each parameter θⱼ.
- The derivation involves applying the chain rule to the log likelihood function, the sigmoid function, and the linear combination of features and parameters.
- Simplified Derivative: The simplified partial derivative is ∂J/∂θⱼ = 1/m * ∑ᵢ (yᵢ - h(xᵢ)) * xᵢⱼ.
- Gradient Vector: The gradient is a vector containing the partial derivatives of the loss function with respect to all parameters.
- Parameter Update: θ := θ - α * ∇J(θ), where α is the learning rate and ∇J(θ) is the gradient.
- Learning Rate: Controls the step size during gradient descent. A smaller learning rate leads to slower convergence but may avoid overshooting the minimum.
- Matrix Notation: The gradient can be expressed in matrix form for efficient computation: ∇J(θ) = 1/m * Xᵀ * (Y - H), where X is the feature matrix, Y is the vector of true labels, and H is the vector of predicted probabilities.
4. Python Implementation from Scratch
- Libraries: Only NumPy is used for efficient vector and matrix operations.
- Sigmoid Function Implementation:
import numpy as np def sigmoid(z): return 1.0 / (1 + np.exp(-z)) - Gradient Calculation Implementation:
def calculate_gradient(theta, X, y): m = y.size h = sigmoid(X @ theta) gradient = (X.T @ (h - y)) / m return gradient - Gradient Descent Implementation:
def gradient_descent(X, y, alpha=0.1, num_iterations=100, tolerance=1e-6): X_b = np.c_[np.ones((X.shape[0], 1)), X] # Add bias term theta = np.zeros(X_b.shape[1]) for i in range(num_iterations): gradient = calculate_gradient(theta, X_b, y) theta = theta - alpha * gradient if np.linalg.norm(gradient) < tolerance: break return theta - Prediction Implementation:
def predict_proba(X, theta): X_b = np.c_[np.ones((X.shape[0], 1)), X] # Add bias term return sigmoid(X_b @ theta) def predict(X, theta, threshold=0.5): return (predict_proba(X, theta) >= threshold).astype(int) - Data Preprocessing: The breast cancer dataset from scikit-learn is used for evaluation. The data is split into training and testing sets and scaled using
StandardScaler. - Training and Evaluation: The
gradient_descentfunction is used to train the logistic regression model. Thepredictfunction is used to make predictions on the test set. The accuracy score is used to evaluate the model's performance.
5. Example and Evaluation
- Dataset: Breast cancer dataset from scikit-learn.
- Preprocessing: Data is scaled using
StandardScaler. - Evaluation Metric: Accuracy score.
- Results: Achieved a training accuracy of 98.25% and a testing accuracy of 97.36% with the implemented logistic regression. Reducing the number of iterations to one resulted in a lower accuracy of 93%, demonstrating the impact of gradient descent iterations.
6. Conclusion
The video provides a comprehensive guide to implementing logistic regression from scratch in Python. It covers the theoretical foundations, mathematical derivations, and practical implementation details. By combining linear regression with the sigmoid function and optimizing the cross-entropy loss function using gradient descent, the implemented model achieves high accuracy on the breast cancer dataset. The video emphasizes understanding the underlying mathematics and implementing the algorithm without relying on pre-built machine learning libraries.
AI summaries can miss context or contain errors. Check important details against the original video.