Key Concepts
Logistic Regression, Binary Classification, Probability, Linear Regression, Sigmoid Function, Logit, Parameters (Theta), Bias/Intercept, Likelihood Function, Log Likelihood, Cross-Entropy Loss Function, Gradient Descent, Partial Derivatives, Chain Rule, Learning Rate, Matrix/Vector Notation.
1. Theoretical Foundations of Logistic Regression
- Logistic Regression as Classification: Despite the name, logistic regression is a classification algorithm used to predict probabilities of class membership (typically binary: 0 or 1).
- Probability Output: Instead of directly outputting a class label, it outputs a probability between 0 and 1, representing the likelihood of an instance belonging to a specific class (e.g., 0.768 probability of being a cat).
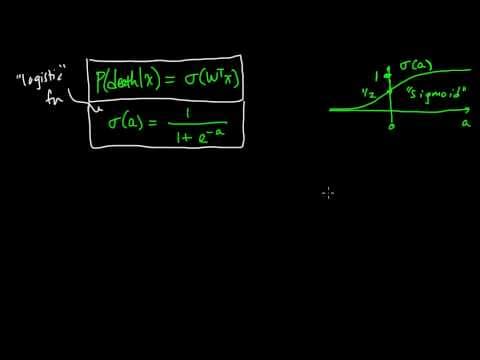
- Linear Regression with Sigmoid: Logistic regression combines linear regression with a sigmoid function to constrain the output between 0 and 1.
- Input Features (X): Each instance i has n features (e.g., study hours, previous test score). These features are represented as a vector x_i. There are m total instances.
- Parameters (Theta): A vector of parameters (θ) or coefficients, one for each feature, plus a bias/intercept term. These parameters are what the model learns during training.
- Logit (Z): The linear combination of input features and parameters: z_i = θ<sup>T</sup> x_i. This is the output of the linear regression part.
- Sigmoid Function: The sigmoid function, σ(z) = 1 / (1 + e<sup>-z</sup>), maps the logit z to a probability between 0 and 1.
- Estimated Probability (h): The output of the sigmoid function, h(x_i; θ) = σ(z_i), is the estimated probability that instance i belongs to class 1.
2. Deriving the Cross-Entropy Loss Function
- Need for Optimization: The raw probability output h cannot be directly optimized. A loss function is needed to quantify the error between predicted probabilities and actual class labels.
- Likelihood Function: The likelihood function, L(θ), measures how well the parameters θ fit the data. It's the product of probabilities of observing the actual outcomes given the predicted probabilities.
- L(θ) = Π<sub>i=1</sub><sup>m</sup> h(x_i; θ)<sup>y_i</sup> * (1 - h(x_i; θ))<sup>(1 - y_i)</sup>, where y_i is the true class label (0 or 1).
- Modifications for Optimization: The likelihood function is modified for optimization purposes:
- Negation: Multiply by -1 to convert maximization to minimization (for gradient descent).
- Logarithm: Take the natural logarithm (ln) for numerical stability and to convert the product into a sum.
- Scaling: Divide by m to make the loss scale-invariant.
- Log Likelihood Function: Applying the logarithm transforms the likelihood function into the log-likelihood function. Using properties of logarithms (ln(a*b) = ln(a) + ln(b) and ln(a<sup>b</sup>) = b*ln(a)), the log-likelihood becomes a sum of terms involving logarithms of h and (1-h).
- Cross-Entropy Loss Function (J): The final loss function, J(θ), is the negative average log-likelihood, also known as the cross-entropy loss:
- J(θ) = -1/m Σ<sub>i=1</sub><sup>m</sup> [y_i log(h(x_i; θ)) + (1 - y_i) log(1 - h(x_i; θ))]
- This is the function to be minimized during training.
3. Gradient Descent and Parameter Optimization
- Goal: Find the optimal parameters (θ) that minimize the cross-entropy loss function J(θ).
- Gradient Descent: An iterative optimization algorithm that updates the parameters in the direction of the steepest descent of the loss function.
- Partial Derivatives: Calculate the partial derivative of the loss function with respect to each parameter θ_j. This indicates how changing θ_j affects the loss.
- Chain Rule: Apply the chain rule of calculus to compute the partial derivatives: ∂J/∂θ_j = (∂J/∂h) * (∂h/∂z) * (∂z/∂θ_j).
- ∂J/∂h: How the loss function changes with respect to the predicted probability h.
- ∂h/∂z: How the predicted probability h (sigmoid output) changes with respect to the logit z. This is the derivative of the sigmoid function, which is σ(z) * (1 - σ(z)) or simply h*(1-h).
- ∂z/∂θ_j: How the logit z changes with respect to the parameter θ_j. This is simply the input feature x_j.
- Simplified Derivative: After applying the chain rule and simplifying, the partial derivative of the loss function with respect to θ_j becomes: ∂J/∂θ_j = 1/m Σ<sub>i=1</sub><sup>m</sup> (h(x_i; θ) - y_i) * x_ij.
- Gradient Vector: The gradient is a vector containing all the partial derivatives. It points in the direction of the steepest ascent of the loss function.
- Parameter Update: Update the parameters iteratively: θ := θ - α ∇J(θ), where α is the learning rate (controls the step size).
- Learning Rate (α): A hyperparameter that determines the size of the steps taken during gradient descent. A smaller learning rate may lead to slower convergence, while a larger learning rate may cause the algorithm to overshoot the minimum.
4. Python Implementation from Scratch
- Libraries: Only NumPy is used for efficient vector and matrix operations.
- Sigmoid Function: Implemented as
sigmoid(z) = 1 / (1 + np.exp(-z)). calculate_gradient(theta, X, y)Function:- Calculates the gradient of the cross-entropy loss function.
m = y.size(number of instances).return (X.T @ (sigmoid(X @ theta) - y)) / m(matrix notation for the gradient).
gradient_descent(X, y, alpha=0.1, num_iterations=100, tolerance=1e-4)Function:- Implements the gradient descent algorithm.
- Adds a bias term to the input features (prepends a column of ones to X).
- Initializes the parameters (theta) to zeros.
- Iterates
num_iterationstimes:- Calculates the gradient using
calculate_gradient(). - Updates the parameters:
theta -= alpha * gradient. - Optional early stopping: If the magnitude of the gradient is below the
tolerance, the loop breaks.
- Calculates the gradient using
- Returns the trained parameters (theta).
predict_proba(X, theta)Function:- Predicts the probability of class membership for new instances.
- Adds a bias term to the input features.
- Calculates the predicted probability using the sigmoid function:
sigmoid(X @ theta).
predict(X, theta, threshold=0.5)Function:- Predicts the class label (0 or 1) based on the predicted probability and a threshold.
- Returns 1 if the predicted probability is above or equal to the threshold, 0 otherwise.
5. Evaluation with Scikit-learn
- Data Set: The breast cancer data set from scikit-learn is used for evaluation.
- Data Preprocessing:
train_test_split: Splits the data into training and testing sets (80% training, 20% testing).StandardScaler: Scales the features to have zero mean and unit variance.
- Training: The
gradient_descent()function is used to train the logistic regression model on the scaled training data. - Prediction: The
predict()function is used to make predictions on the scaled training and testing data. - Evaluation Metric: The
accuracy_score()function from scikit-learn is used to evaluate the performance of the model on the training and testing sets. - Results: The implemented logistic regression model achieves high accuracy on both the training and testing sets (e.g., 98.25% training accuracy, 97.36% testing accuracy).
6. Notable Quotes
- "Even though the name is regression it's actually a classification algorithm."
- "If you're watching this video you want to understand it from scratch so it makes sense to also understand the mathematics."
- "This here is called the cross entropy loss function this is something we often times use when training neural networks."
7. Technical Terms and Concepts
- Logistic Regression: A statistical method for binary classification that models the probability of a binary outcome.
- Sigmoid Function: A mathematical function that maps any real value to a value between 0 and 1.
- Logit: The logarithm of the odds, used as the linear predictor in logistic regression.
- Cross-Entropy Loss: A loss function used in classification tasks, measuring the difference between predicted and actual probability distributions.
- Gradient Descent: An iterative optimization algorithm used to find the minimum of a function.
- Partial Derivative: The derivative of a function with respect to one variable, holding other variables constant.
- Chain Rule: A rule in calculus for differentiating composite functions.
- Learning Rate: A hyperparameter that controls the step size in gradient descent.
8. Logical Connections
The video progresses logically from the theoretical foundations of logistic regression to its practical implementation in Python. It starts by explaining the core concepts, then derives the necessary mathematical formulas, and finally translates these formulas into code. The evaluation section demonstrates the effectiveness of the implemented algorithm.
9. Synthesis/Conclusion
The video provides a comprehensive guide to implementing logistic regression from scratch in Python. It covers the theoretical underpinnings, including the derivation of the cross-entropy loss function and the gradient descent algorithm. The Python implementation demonstrates how to translate these concepts into code, and the evaluation section confirms the effectiveness of the implemented algorithm. The video emphasizes understanding the underlying mathematics and provides a step-by-step approach to building a logistic regression model without relying on external machine learning libraries.
AI summaries can miss context or contain errors. Check important details against the original video.