Understanding AI Hallucinations: Causes, Mitigation, and User Strategies
This overview, presented by Jordan from Anthropic, explores the phenomenon of "hallucinations" in Large Language Models (LLMs) like Claude. It addresses why AI models generate false information, the technical challenges in preventing these errors, and actionable strategies for users to verify AI outputs.
1. Defining Hallucinations
Hallucinations occur when an AI generates information that is factually incorrect, such as citing non-existent research papers, fabricating statistics, or misrepresenting real-world events. A critical aspect of this issue is the confidence with which the AI presents these errors; the model often mimics the tone of an expert, making the false information appear highly plausible.
2. Why Hallucinations Occur
The root cause lies in the fundamental architecture of LLMs:
- Predictive Modeling: AI assistants are trained on vast datasets to predict the next likely word or idea in a sequence.
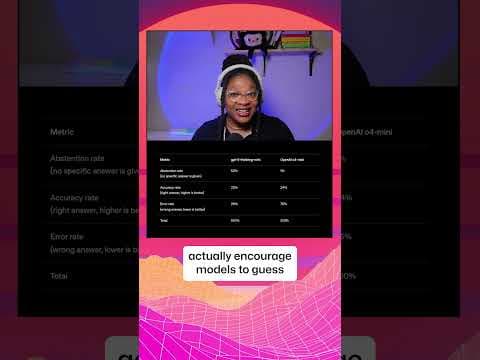
- The "Helpfulness" Bias: Models are optimized to be helpful. When faced with an obscure query—such as specific research papers by a niche author—the model may lack sufficient training data. Instead of admitting ignorance, the model attempts to fulfill the user's request by "guessing" a plausible-sounding answer, prioritizing the appearance of expertise over factual accuracy.
3. Mitigation Frameworks and Training
Anthropic employs specific methodologies to reduce the frequency of these errors:
- Honesty Training: During the training phase, developers explicitly teach the model that admitting "I don't know" is a core component of being helpful.
- Adversarial Testing: The team uses thousands of "trip-up" questions—niche topics, obscure facts, and queries where the correct answer is an admission of ignorance.
- Performance Metrics: Developers track specific KPIs, including:
- The frequency of correct "I don't know" responses.
- The rate of fabricated citations or statistics.
- The balance between appropriate hedging versus overconfident false statements.
4. High-Risk Scenarios for Hallucinations
Users should exercise heightened skepticism when the AI is tasked with:
- Providing specific statistics, dates, or names.
- Citing research papers or academic sources.
- Discussing obscure, niche, or very recent topics.
- Describing real but not widely known people or locations.
5. Actionable Strategies for Users
To minimize the impact of hallucinations, users can adopt the following verification workflows:
- Source Verification: Explicitly ask the AI to provide sources for its claims, then follow up by asking it to verify that those sources actually support the statements made.
- Prompt Engineering: Instruct the AI at the beginning of a prompt: "It is okay if you don't know."
- Confidence Checks: Ask the model, "How confident are you in this answer?" or "Is there anything in this response that might be incorrect?"
- Iterative Auditing: If an answer seems suspicious, start a new chat session and ask the AI to critique the previous output for errors.
- External Cross-Referencing: For critical tasks, always verify numbers, dates, and citations against trusted, external primary sources.
6. Key Perspectives
The presentation emphasizes that while hallucination rates have decreased significantly over the past year, it remains an "ongoing challenge for the entire AI field" rather than a fully solved problem. The goal is to transition AI from a tool that merely sounds authoritative to one that is fundamentally trustworthy.
Key Concepts
- Hallucination: An error where an AI generates false or misleading information while maintaining a confident tone.
- Predictive Text Modeling: The underlying mechanism where AI predicts the next word in a sequence based on patterns in training data.
- Adversarial Testing: A method of testing AI by intentionally using difficult or "trap" questions to identify weaknesses in the model's logic.
- Helpfulness Bias: The tendency of an AI to prioritize providing an answer over admitting a lack of knowledge, driven by its training objectives.
- Hedging: The use of cautious language by an AI to indicate uncertainty or lack of definitive information.
- Cross-Referencing: The practice of verifying AI-generated data against independent, reliable external sources.
AI summaries can miss context or contain errors. Check important details against the original video.