Key Concepts:
- Reliable Systems
- Failure Modes
- Graceful Degradation
- User Experience (UX)
- System Dependencies
- Redundancy (Caching, Alternative Paths)
What Does a Reliable System Mean for an SRE?
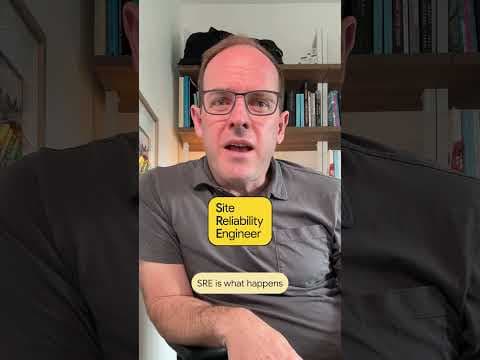
For a Site Reliability Engineer (SRE), a reliable system signifies the ability to consistently deliver service to users, even in the face of failures. It's about proactively anticipating and mitigating potential issues that could lead to catastrophic outages. The core principle is to "rescue users from catastrophic failures."
How to Build a Reliable System
The process of building reliable systems involves anticipating failure modes and implementing defenses against them. This is illustrated through the analogy of a firefighter, who intervenes to prevent disaster.
- Anticipating Failures: A reliable system doesn't assume that its dependencies will always be available. It acknowledges that components can fail.
- Defending Against Failures: This involves building in mechanisms to handle these anticipated failures. Examples include:
- Caching: Storing frequently accessed data locally to reduce reliance on the primary storage system.
- Alternative Paths: Designing the system to switch to a different instance or a completely different service if the primary one becomes unavailable.
User Experience and Graceful Degradation
A fundamental aspect of reliable systems is respecting the user and ensuring a positive, or at least understandable, experience even when things go wrong. This is achieved through graceful degradation.
- Failure Modes and User Impact: When systems fail, users typically encounter negative experiences such as:
- Stalled applications ("stag dyno")
- "404 Not Found" pages
- Endless loading spinners
- Graceful Degradation: Instead of a complete outage, a reliable system will degrade its functionality in a controlled manner. The example provided is an app for sharing cat photos:
- If the storage system fails, the app might display an image of a "catnapping" cat.
- Crucially, it would provide a clear message to the user: "Taking a catnap. Be back soon." This manages user expectations and informs them about the temporary issue.
Supporting Resources
For further information on designing reliable systems, the transcript directs readers to the website: surre.google/re. Google/resources.
Synthesis/Conclusion
Building reliable systems is a core responsibility for SREs, focusing on user protection and service continuity. It requires a proactive approach to anticipating and defending against system failures through mechanisms like caching and redundant paths. The ultimate goal is to ensure that systems degrade gracefully, minimizing user impact and maintaining trust by communicating transparently during outages.
AI summaries can miss context or contain errors. Check important details against the original video.