Key Concepts:
- RAG (Retrieval-Augmented Generation) agents
- Document chunking
- Vector database
- Markdown format
- Recursive character splitter
- N8N (No-Code Automation Platform)
Improving RAG Agent Effectiveness with Markdown Chunking
The video focuses on a simple adjustment to improve the effectiveness of RAG agents by optimizing document chunking. The core problem addressed is that default chunking methods in RAG systems can lead to chunks that are out of context, negatively impacting retrieval and generation.
1. The Problem: Default Chunking and Context Loss
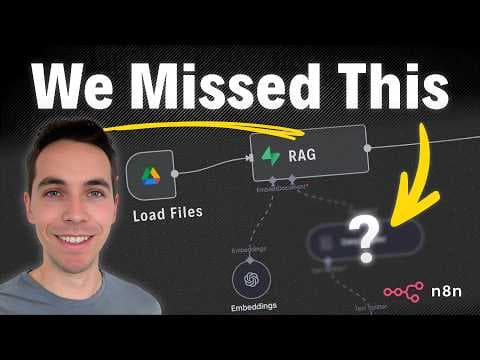
- In a standard RAG setup, documents are loaded, split into chunks, and stored in a vector database.
- Default chunking often involves splitting documents into roughly 1000-character segments with some overlap.
- Without proper formatting, these chunks can be arbitrary and lack contextual coherence.
2. The Solution: Markdown-Based Chunking
- The proposed solution involves converting documents into markdown format before chunking.
- The key is to use a data loader that prioritizes headings during the chunking process. This ensures that chunks start with headings, providing immediate context.
3. Step-by-Step Implementation in N8N
- Add a Default Data Loader: This is the initial step in the N8N workflow.
- Add a Recursive Character Splitter: This node is responsible for the actual chunking.
- Crucial Step: Activating Markdown Chunking:
- Click into the Recursive Character Splitter node.
- Press the "add option" button once.
- Select "markdown" as the default option.
- Explanation of the "Add Option" Button: The video emphasizes that selecting "markdown" from the dropdown list without first pressing the "add option" button does not actually activate markdown chunking. The N8N code confirms this behavior.
- Save and Execute: After correctly configuring the markdown option, save the workflow and execute it.
4. Verification and Results
- Chunk Inspection: After execution, examine the generated chunks. They should now be correctly chunked by headings, ensuring contextual integrity.
- Improved Retrieval: The video asserts that these contextually rich chunks will lead to more relevant results when querying the vector store.
5. Data Preparation (Referenced Video)
- The video mentions a separate video that explains how to prepare various data sources (Google Docs, PDFs, web pages) and convert them into markdown format. This is a prerequisite for the described chunking method.
6. Technical Terms Explained
- RAG (Retrieval-Augmented Generation): A framework where a language model retrieves information from an external knowledge base (vector database) to improve the quality and relevance of its generated text.
- Vector Database: A database that stores data as vectors, enabling efficient similarity searches for retrieval.
- Markdown: A lightweight markup language with plain text formatting syntax.
- Recursive Character Splitter: A tool that splits text into smaller chunks based on character count, often with options to prioritize certain characters or patterns (like headings).
7. Logical Connections
The video establishes a clear chain of reasoning:
- Default chunking leads to context loss.
- Markdown-based chunking, prioritizing headings, preserves context.
- Correct configuration of the Recursive Character Splitter in N8N is essential for activating markdown chunking.
- Contextually rich chunks improve retrieval and, consequently, RAG agent performance.
8. Synthesis/Conclusion
The video demonstrates a simple yet impactful technique for enhancing RAG agent performance. By correctly configuring markdown-based chunking in N8N, users can ensure that document chunks retain contextual information, leading to more relevant and accurate retrieval results. The key takeaway is the importance of the "add option" button when configuring the Recursive Character Splitter to properly activate markdown chunking.
AI summaries can miss context or contain errors. Check important details against the original video.