THE SUMMARYAI-generated
Key Concepts:
- No-Code Automation: Building automated workflows without writing code.
- Web Scraping: Extracting data from websites.
- Bright Data: A web data platform used for proxy and web scraping services.
- NADN: A no-code automation platform.
- OpenAI Node: Using OpenAI's models (like GPT-4) for text summarization and data extraction.
- Google Sheets Integration: Outputting scraped data to a Google Sheet.
- Data Extraction Schema: Defining the structure of data to be extracted by AI.
- HTTP Request Node: Sending requests to external APIs (like Bright Data).
- Split Item Node: Splitting a list of items into individual data rows.
1. Introduction
- The video demonstrates how to automate the process of identifying top-selling products on Amazon using AI and no-code tools.
- The goal is to create a system that automatically sends daily updates on top-selling products in specific niches (e.g., home improvement, electronics) to the user's email or Google Sheet.
- The solution is built using NADN, a no-code platform, making it accessible to users without programming experience.
2. Overview of the Automated Workflow
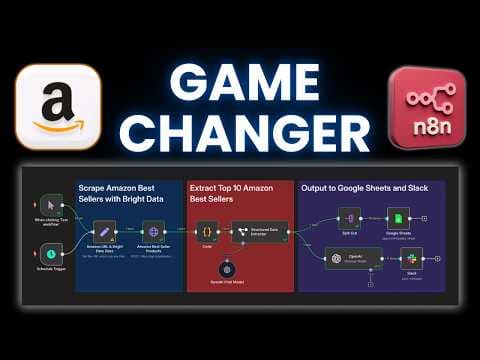
- The workflow involves scraping Amazon product pages, extracting relevant data, summarizing it using AI, and outputting the results to a Google Sheet and/or a Slack channel.
- The process is designed to be fully automated, running daily without manual intervention once set up.
3. Setting Up the NADN Workflow
- Creating a NADN Account: Users are directed to sign up for a free 14-day trial of NADN via a link in the video description.
- Importing a Blueprint (JSON File): The video demonstrates how to import a pre-built workflow blueprint (JSON file) into NADN to quickly set up the automation. This blueprint contains all the necessary nodes and configurations.
- The blueprint is available to members of the creator's community.
- Manual vs. Scheduled Trigger: The video uses a manual trigger ("When clicking a test workflow") for demonstration purposes. For production use, a scheduled trigger is recommended to automate the process daily.
4. Web Scraping with Bright Data
- Bright Data Account Setup: Users are instructed to create a Bright Data account to access web scraping tools. A free trial is available.
- Creating a Web Unlocker Zone: Within Bright Data, a "Web Unlocker API" zone is created. This zone allows the user to scrape websites without being blocked.
- The zone requires a name (lowercase) and generates an API token.
- Set Node Configuration: A "Set" node in NADN is used to define variables:
zone: Stores the name of the Bright Data Web Unlocker zone.URL: Stores the Amazon URL to be scraped (e.g., the URL for "Bestsellers in Home & Kitchen").
- HTTP Request Node Configuration: An "HTTP Request" node is configured to send a POST request to the Bright Data API:
- Method: POST
- URL:
api.brightdata.com/request - Authentication: Header with "Authorization" set to "Bearer [API Token]"
- Body:
zone: The Bright Data zone name.URL: The Amazon URL to scrape.format: Set to "raw".
5. Data Extraction and Summarization with OpenAI
- Code Node for HTML Sampling: A "Code" node is used to extract a sample of HTML from the scraped data. This is done to reduce the amount of data sent to the OpenAI node, improving efficiency.
- The code (provided in the video description or community) uses JavaScript to grab a partial HTML structure.
- Information Extractor Node (OpenAI): An "Information Extractor" node is used to extract structured data from the HTML sample using OpenAI's models.
- Model: GPT-4 (or similar) is used for its ability to understand and extract data from unstructured text.
- Schema Definition: A schema is defined to specify the data fields to extract (e.g., title, stars, total ratings, offer, product URL, image URL). The schema is provided in the video description or community.
- Split Item Node: A "Split Item" node is used to split the output from the OpenAI node into individual items (rows), making it easier to process and output to a Google Sheet.
6. Outputting Data to Google Sheets
- Google Sheets Node Configuration: A "Google Sheets" node is configured to append or update rows in a Google Sheet.
- Credentials: Google Sheets credentials are set up to allow NADN to access the sheet.
- Resource: "Sheet within document"
- Operation: "Append or update row from list"
- Document ID: The ID of the Google Sheet.
- Sheet Name: The name of the sheet within the document (e.g., "Sheet1").
- Column to Match On: A column to use for matching rows (e.g., "ranking").
- Column Mapping: Data fields from the "Split Item" node are mapped to the corresponding columns in the Google Sheet (e.g., title to title, stars to stars).
- Google Sheet Template: A Google Sheet template is provided to ensure the correct column names and structure for the data.
7. Optional: Slack Integration for Summarized Updates
- Message a Model Node (OpenAI): A "Message a Model" node is used to generate a summarized update of the top-selling products using OpenAI.
- Model: A smaller model like "nano" can be used for faster processing.
- Prompt: A prompt is defined to instruct the AI to summarize the top 10 products.
- Slack Node: A "Slack" node is used to send the summarized update to a Slack channel or user.
8. Example and Customization
- The video demonstrates how to change the Amazon URL to scrape different product categories (e.g., clothing).
- The process is the same: update the URL in the "Set" node, and the workflow will automatically scrape and extract data for the new category.
9. Conclusion
- The video provides a step-by-step guide to automating the process of identifying top-selling products on Amazon using no-code tools and AI.
- The solution can be customized to track different product categories and output data to Google Sheets and/or Slack.
- The automated workflow saves time and effort by eliminating the need to manually monitor Amazon product pages.
AI summaries can miss context or contain errors. Check important details against the original video.