Key Concepts
- Learning-based multi-robot control
- Scalability, distributed execution, and explanability in multi-robot systems
- Local policies and homogeneous policies
- Self-attention mechanism for handling varying neighborhood sizes
- Port Hamiltonian systems for modeling physical interactions
- Physics-informed learning paradigm
- Learning closed-loop dynamics
- Passivity-based control
- Imitation learning and reinforcement learning frameworks
- Generative AI for high-level planning in drone swarms
- Diffusion models and conditional flow matching
- Collision avoidance and trajectory feasibility
Multi-Robot Control via Physics-Informed Self-Attention
Introduction
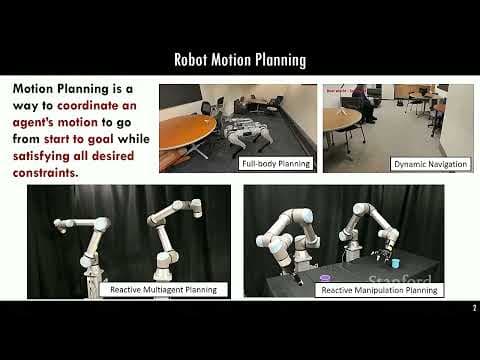
The presentation focuses on learning to control large teams of robots, addressing the challenges of scalability, distributed execution, and explanability. The work aims to move beyond handcrafted algorithms like flocking, which are insufficient for modeling complex interactions in dynamic environments.
Related Work
- Autonomous Drone Cinematography: Developed solutions for controlling drone movement and camera parameters (focus distance, focal length, aperture) to achieve cinematographic effects.
- Distributed Tracking and Classification: Combined control-theoretical methods (distributed Kalman filtering) with real-world tracking considerations (data association, bandwidth). Extended to active perception with static and dynamic cameras for object classification.
- Active Perception: Developed representations for reasoning about optimal robot positions to improve the output of neural networks for tasks like object classification.
- Optimal Collision Avoidance: Developed a solution for navigating in dynamic environments without knowing the intentions of other agents, estimating their cooperativeness based on onboard sensing.
Research Question
How to efficiently learn multi-robot policies capable of modeling complex interactions?
Desired Properties of Learning-Based Solutions
- Scalability: The solution should work for varying numbers of robots (e.g., 3 to 3000).
- Distributed Execution: Each agent should make decisions based on locally available information.
- Explanability: The model should incorporate physical properties and constraints of the robots and the environment.
Proposed Approach: Physics-Informed Self-Attention
- Scalability: Achieved through local policies, where each robot has its own policy that considers information from nearby agents. Homogeneous policies are assumed, meaning the same policy is used for all robots.
- Distributed Execution: Inspired by Large Language Models (LLMs) and self-attention mechanisms. Each agent is treated as a "token," and self-attention is used to weight the relationships between agents based on locally available information. This handles time-varying neighborhood sizes.
- Explanability: Utilizes port Hamiltonian systems to model the dynamics of the multi-agent system. This incorporates physical properties and ensures that the system evolves towards a minimum energy configuration.
Port Hamiltonian Systems
- The system's dynamics are described by the equation:
ẋ = [J(θ) - R(θ)]∇H(x) + G(θ)u, where:xis the state vector (position and velocity of each agent).Jis the interconnection matrix.Ris the dissipation matrix.His the Hamiltonian (total energy of the system).Gis the input matrix.uis the local input.θrepresents the parameters learned by neural networks.
- Port Hamiltonian systems have the property that the interconnection of multiple port Hamiltonian systems is also a port Hamiltonian system.
Physics-Informed Learning Paradigm
- Instead of estimating the matrices
J,R, andHthrough system identification, they are parameterized by neural networks and learned from data. - The learning framework focuses on learning the closed-loop dynamics of the system, rather than the open-loop dynamics. This allows learning from external observations (e.g., videos) without needing to know the actions applied by the agents.
- Passivity-based control is used to transform the learned closed-loop dynamics into open-loop dynamics and extract the local inputs for each robot.
Local Policy Implementation
- The global matrices
J,R, andHare decomposed into local sub-matrices that are learned by individual neural networks. - Each agent learns the sub-matrices corresponding to the agents it has information about.
- If an agent has no information about another agent, the corresponding terms in the matrices are set to zero.
Overall Architecture
- Each robot has its own information and information from neighbors.
- A multi-head self-attention mechanism is used to infer the matrices
J,R, andH.- One head learns
J. - One head learns
R. - One head learns
H.
- One head learns
- The Hamiltonian
His assumed to be the sum of local Hamiltonians. - Passivity-based control is used to obtain the local individual actions from the learned closed-loop dynamics.
Experimental Results
- Imitation Learning: The system was trained on demonstrations of navigation and flocking tasks. It was able to generalize to different numbers of robots (up to 64).
- Reinforcement Learning: A physics-informed actor-critic was developed, where the actor uses the physics-informed multi-head self-attention architecture. The system was trained in a simulator (Vimma) and tested on navigation, coverage, transportation, and competitive scenarios.
- Realistic Physics Engine: The system was applied to the half-cheetah problem in MuJoCo, treating the joints as agents.
- Real-World Experiments: The system was trained in simulation with holonomic vehicles and transferred to real robots with non-holonomic constraints.
Limitations
- In the coverage task, some agents learned to do nothing.
- The system may not work well with heterogeneous behaviors.
Generative AI for Drone Swarm Art Shows
Research Question
How to create and achieve desired configurations for multi-robot teams in a simple way, similar to how DALL-E generates images from prompts?
Approach
Extend the concept of DALL-E to swarms by using diffusion models to generate 3D point clouds representing the desired formations.
Diffusion Models
- Self-supervised methods that learn to denoise images.
- During training, noise is incrementally added to images.
- The model learns to reverse this process and generate images from noise.
- During inference, the model starts with a random image and iteratively denoises it to obtain the desired image.
Adapting Diffusion Models to Swarms
- Pixels to Robots: Treat robots as pixels in a 3D space.
- Images to Point Clouds: Train the model on point clouds instead of images.
- 3D Positions: Generate 3D positions for the robots.
Challenges
- Collision Avoidance: Robots cannot occupy the same position.
- Trajectory Feasibility: The generated trajectories must be physically possible for the robots to follow.
Evaluation Metrics
- 3D Shape Quality: Measured by the Chamfer distance between the final point cloud and the desired shape.
- Collision Avoidance: Measured by the number of collisions between robots.
- Trajectory Feasibility: Measured by the smoothness of the trajectories.
Approaches and Results
- DDPM 3D: Generates high-quality shapes but results in collisions and infeasible trajectories.
- DDPM 3D + ORCA: Uses Optimal Reciprocal Collision Avoidance (ORCA) for reactive navigation to avoid collisions. This results in smooth trajectories and collision avoidance but slower convergence and lower shape quality.
- Conditional Flow Matching (CFM): Learns the velocity at which the pixels should change in continuous time. This results in smooth trajectories but still has collision issues.
- Gen Swarms (CFM + ORCA): Uses CFM to generate desired velocities and ORCA to apply the closest safe velocity at each time step. This achieves high shape quality, smooth trajectories, and collision avoidance.
Limitations
- The system is trained on a specific number of time steps and may not be time-agnostic.
- The conditional flow matching algorithm tends to generate straight-line motions, which may not be optimal for robot dynamics.
- Doesn't work if starting from a different drone configuration.
Conclusion
The presentation showcased two solutions for learning to control large teams of robots: a physics-informed approach for distributed control policies and a generative AI algorithm for high-level reference trajectories in drone art shows. Both approaches offer promising avenues for future research and applications in multi-robot systems.
AI summaries can miss context or contain errors. Check important details against the original video.