THE SUMMARYAI-generated
Key Concepts
- Pre-training: Training on raw, often web-scraped data.
- Mid-training: Curating a smaller, high-quality dataset for specific capabilities.
- Post-training: Fine-tuning for instruction following, chat, or safety.
- Base Model: Checkpoint after pre-training and mid-training.
- Instruction Model: Model after post-training.
- Common Crawl: Monthly web crawl, an academic approximation of the internet.
- Data Poisoning: Injecting malicious edits into training data.
- Quality Filtering: Using heuristics or models to select high-quality data.
- Deduplication: Removing duplicate content from the dataset.
- Fair Use: Using copyrighted material without a license under certain conditions.
- Long Context Extension: Training models to handle longer sequences of text.
- Synthetic Data: Data generated by language models for training.
Pre-training Data
Importance of Data
- Data is arguably the most important factor in language model performance.
- Companies are secretive about their training data due to competitive dynamics and legal concerns.
- Data curation and cleaning are crucial, even with less annotation.
- Data work is highly scalable and can involve large teams focusing on different aspects like multilinguality and code.
Stages of Training
- Pre-training: Training on raw data from the web.
- Mid-training: Curating high-quality data for specific capabilities (math, code, long context).
- Post-training: Fine-tuning on instruction following data, chat data, or using reinforcement learning for safety and conversational ability.
Example Data Mixes
- AI2's OMO Model:
- Pre-training: Web pages (DCL on baseline), code, academic papers, math, Wikipedia (3.9 trillion tokens).
- Mid-training: Filtered DCL on baseline, Flan data sets, Wikipedia, synthetically generated data, GSM8K training set (10 billion tokens).
- Post-training: Chat data from various sources, synthetically generated data.
Early Data Sets (2018-2019)
- BERT: Trained on books (Smashwords corpus) and Wikipedia.
- Books corpus: Scraped from Smashwords, consisting of self-published ebooks.
- Wikipedia: A collaborative encyclopedia with no original thought, based on citations and notability.
- Data Poisoning: Vulnerability where malicious edits can be injected into Wikipedia dumps.
- GPT-2: Used WebText, a dataset of links from Reddit posts with more than three karma points.
Common Crawl and Filtering
- Common Crawl: Established in 2007, monthly web crawl.
- Crawling process: Uses a BFS approach with seed URLs, respecting robots.txt.
- Data formats: WARC (raw HTTP response) and WET (text extracted from HTML).
- HTML to text conversion: Using raw WARC files with tools like Trafilatura can improve performance.
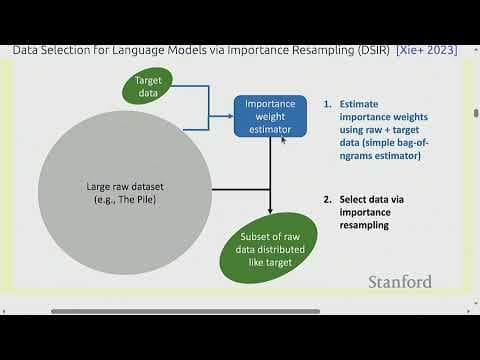
- CCNet (Meta): Filters Common Crawl using language identification and a 5-gram model based on Wikipedia to identify high-quality documents.
- C4 (Google): Colossal Clean Crawled Corpus, filtered using heuristics (punctuation, sentence length, bad words, brace removal).
- Trade-off: Model-based filtering (CCNet) vs. rule-based filtering (C4). Model-based is limited by the quality of positive examples, while rule-based can include spam or exclude valuable content.
GPT-3 Era (2020)
- GPT-3 Data Set: Common Crawl, processed WebText2, books corpora, and Wikipedia (400 billion tokens).
- Quality classification: Trained a classifier to distinguish high-quality web data, Wikipedia, and books from the rest.
- The Pile (EleutherAI): Curated 22 high-quality domains (Common Crawl, OpenWebText, Stack Exchange, Wikipedia, etc.).
- Project Gutenberg: Collection of public domain books (75,000 books).
- Books3: Books from a shadow library (taken down due to copyright infringement).
- Stack Exchange: Collection of Q&A sites (Stack Overflow, etc.).
- GitHub: Source of code for language model training.
- The Stack: Open-source version of code based on GitHub (3.1 terabytes of code).
Later Data Sets (2021-Present)
- Gopher (DeepMind): Massive Text data set (MassiveWeb, C4, books, news, GitHub, Wikipedia).
- MassiveWeb: Used manual rules for quality filtering and Google Safe Search for toxicity filtering.
- Llama (Meta): Common Crawl processed with CCNet, C4, GitHub, Wikipedia, Project Gutenberg, Books3, Archive, Stack Exchange (1.2 trillion tokens).
- Red Pajama: Open-source reproduction of the Llama data set.
- RefinedWeb: Focuses on filtering web data effectively.
- FineWeb from Hugging Face: Improved version of RefinedWeb, using all Common Crawl dumps and manual rules.
- OMO (AI2): Trained on the Doma data set (Common Crawl, The Stack, C4, Reddit, Semantic Scholar, Project Gutenberg, Wikipedia).
- DataComp (Collaboration): Competition for creating data sets, using Common Crawl.
- DCM Pool: 240 trillion tokens from Common Crawl.
- DCM Baseline: Filtered DCM Pool using a quality filter based on Open Hermes (GPT-4 generated instruction data) and Eli5 (subreddit).
- Neatron CC (Nvidia): Aims to expand the DCLM baseline with more tokens.
- Used JustText for HTML to text conversion to retain more tokens.
- Prompted a large language model to score documents based on educational value.
- Used the DCLM classifier and ensembled different classifiers.
- Rephrased low-quality data sets and generated tasks for high-quality data sets.
Copyright
Copyright Law
- Copyright law incentivizes the creation of intellectual goods.
- Applies to original works of authorship fixed in a tangible medium of expression.
- Copyright applies to expression, not ideas.
- Registration is not required for copyright, but it is required before suing for infringement.
- Copyright lasts 75 years.
- Most things on the internet are copyrighted.
Using Copyrighted Material
- Licensing: Obtain a license from the copyright holder.
- Creative Commons license: Allows free distribution of copyrighted work.
- Fair Use: Use copyrighted material without a license under certain conditions.
- Factors: Purpose and character of the use, nature of the work, amount used, effect on the market.
- Training ML models can be argued as transformative, but models can memorize and affect the market.
- Terms of use can restrict data access even with a license or fair use claim.
Mid-training and Post-training Data
Long Context Extension
- Books and math are used to create data with long-range dependencies.
Instruction Following Data
- Supernatural Instructions and FLAN: Convert traditional NLP benchmarks into a standard format.
- Synthetic data: Generated by language models using self-instruct, conversations, or evol-instruct methods.
- Open Hermes: Glomeration of different data sets.
- Llama 2 Chat: Used annotators to write high-quality instruction data.
- Llama Neatron Postraining Data: Public data sets (WildChat) and synthetically generated data.
Synthetic Data Generation
- GPT-4: Used to generate synthetic data, but it is against the terms of Open AI to use GP4 to create a data set then train a competing model.
- Open-weight models: More permissive licenses for distillation.
- Annotators: Hire annotators to create high-quality instructions.
Conclusion
- Data curation is a crucial and labor-intensive process.
- Data is a key differentiator for language models.
- Legal and ethical issues (copyright) are significant.
- The field is heuristic, with many opportunities for improvement.
AI summaries can miss context or contain errors. Check important details against the original video.
MAKE IT YOURS
Free tools