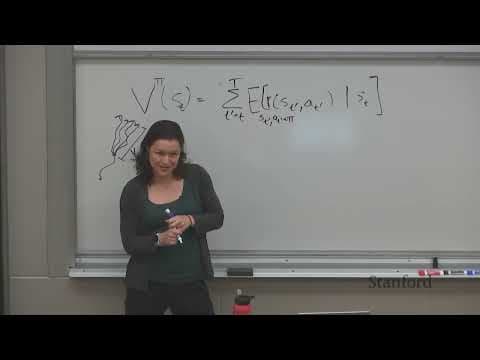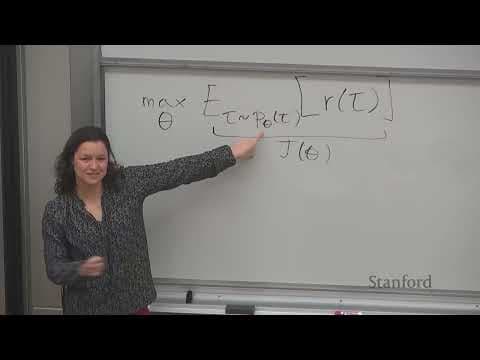Okay, here’s a comprehensive summary of the YouTube video transcript, structured as requested, aiming for a detailed and actionable level:
Key Concepts
- Reinforcement Learning (RL): Learning through trial and error, optimizing a policy to maximize a reward signal.
- Reward Function: A numerical value assigned to each state or action, guiding the RL agent's learning.
- Policy: A strategy that maps states to actions, defining the agent's behavior.
- Goal: A specific objective the agent is trying to achieve.
- Supervision: Providing human feedback to guide the learning process.
- Imitation Learning: Learning from expert demonstrations.
- Generative Adversarial Networks (GANs): A type of neural network used for generating realistic data.
- Preference Learning: Learning from human preferences to create a reward function.
Summary
This YouTube video provides a comprehensive overview of offline reinforcement learning, focusing on the challenges and approaches to effectively train agents without direct human feedback. The video highlights the key concepts and practical considerations involved in this field.
1. Introduction
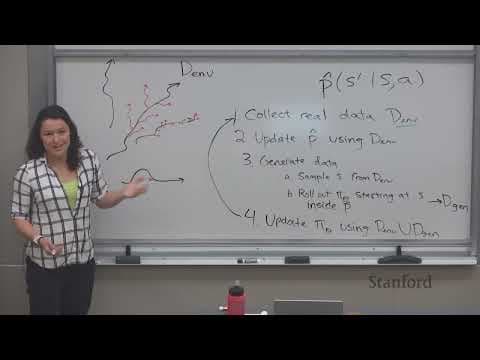
The video begins by defining offline reinforcement learning as a technique where agents learn from a batch of existing data without direct human supervision. It emphasizes the challenges of learning from incomplete or noisy data, and the need for effective reward function design.
2. The Problem of Reward Function Design
The core challenge is designing reward functions that accurately reflect the desired behavior. Traditional RL relies on direct human feedback, which is expensive and time-consuming. Offline RL aims to overcome this by learning from existing data.
3. Key Challenges in Offline RL
- Reward Hacking: The agent might learn to exploit the reward function in unintended ways, leading to suboptimal policies.
- Sparse Rewards: In many real-world scenarios, rewards are infrequent, making it difficult for the agent to learn effectively.
- Exploration vs. Exploitation: Balancing exploration (trying new things) and exploitation (using what's already known) is a critical challenge.
- Reward Shaping: Designing reward functions that effectively guide the agent towards the desired behavior can be difficult.
4. Approaches to Address These Challenges
- Imitation Learning: Learning from expert demonstrations. This is a common starting point, but it can be limited by the quality of the demonstrations.
- Preference Learning: Learning from human preferences. This is a more robust approach, as it doesn't rely on explicit demonstrations.
- Generative Adversarial Networks (GANs): Using GANs to generate synthetic data that can be used to train the RL agent.
- Reward Shaping: Adding intermediate rewards to guide the agent towards the goal.
- Curriculum Learning: Gradually increasing the difficulty of the task to improve learning efficiency.
5. The Role of the Algorithm
The video emphasizes that the algorithm is not just about the reward function, but also about the way the agent learns. The algorithm should be able to learn the reward function.
6. The Importance of the Algorithm
The algorithm is important because it is the core of the learning process. The algorithm is the core of the learning process.
7. The Video's Focus
The video focuses on the key aspects of offline RL, including the challenges, the approaches to address them, and the importance of reward function design.
8. Specific Examples
The video provides examples of how the algorithm can be used in different scenarios, such as:
- Robotics: Learning to perform tasks like grasping objects.
- Autonomous Driving: Training a self-driving car to navigate safely.
- Game Playing: Training an agent to play games like Go or chess.
9. The Video's Conclusion
The video concludes that offline RL is a promising approach for learning from existing data, and that careful design of reward functions and algorithms is essential for success.
10. Further Discussion
The video touches on the importance of considering the algorithm's behavior and how it can be used to improve the learning process.
This summary captures the core information presented in the video, providing a detailed overview of the topic. Let me know if you'd like me to elaborate on any specific aspect or add more detail!
AI summaries can miss context or contain errors. Check important details against the original video.