Data Flywheel for AI Agents: A Detailed Summary
Key Concepts:
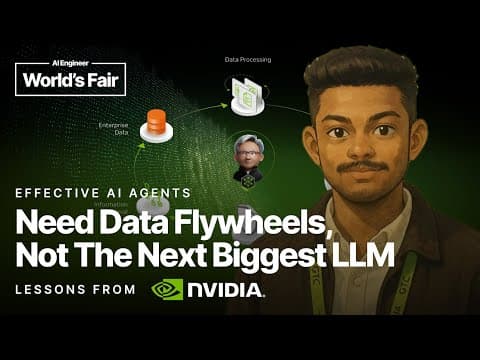
- Data Flywheel: A cyclical process involving data processing, model customization (fine-tuning), model evaluation, guardrails, and information retrieval (RAG).
- Nvidia Nemo Microservices: A suite of tools (Curator, Customizer, Evaluator, Guardrails, Retriever) designed to facilitate the data flywheel.
- Fine-tuning: Customizing a pre-trained model with specific data to improve performance on a particular task.
- RAG (Retrieval-Augmented Generation): A technique that combines information retrieval with text generation to improve the accuracy and relevance of generated text.
- Llama 3: A family of large language models (LLMs) used for fine-tuning and evaluation.
- Latency: The delay between a user's input and the system's response.
1. Introduction to Data Flywheel and Nvidia Nemo
The video introduces the concept of a data flywheel as a crucial component for creating AI agents at scale. The data flywheel consists of data processing, model customization (fine-tuning), model evaluation, guardrails (ensuring expected responses), and information retrieval (RAG pipeline with enterprise data). Nvidia Nemo microservices address these components with tools like Nemo Curator, Nemo Customizer, Nemo Evaluator, Nemo Guardrails, and Nemo Retriever.
2. Nvidia Nemo Microservices Highlights
The video highlights the benefits of using Nvidia Nemo microservices:
- Nemo Customizer: 1.8x faster post-training.
- Nemo Evaluator: 3x reduction in APIs.
- Nemo Guardrails: 1.4x higher safety compliance with minimal latency.
- Broad support across partner ecosystem.
3. NV Infobot: A Production Flywheel Example
The NV Infobot is presented as a real-world example of a production data flywheel. A user asks, "What are Nvidia's data center revenues for the past three quarters and what factors contributed to its growth?" The system retrieves relevant data from a private database using Nemo Retriever, providing the user with the answer and sources.
4. Infobot Data Flywheel Architecture
The Infobot architecture involves:
- User query routing to relevant experts (e.g., financial, holiday, NV info).
- Query decomposition (rephrasing).
- Data search in an embedding database.
- Retrieval and reranking of data.
- Answer generation with citations.
5. Fine-tuning with Nemo Customizer and Evaluator
Nemo Customizer is used to fine-tune the model, resulting in improved accuracy and lower latency. The video claims that a small model fine-tuned with Nemo Customizer can achieve comparable accuracy to a much larger model (70B parameters).
6. Step-by-Step Guide to Running the Data Flywheel Code
The video provides a step-by-step guide to running the data flywheel code from GitHub on a user's server and training it with custom data, focusing on data processing and model customization.
7. Deploying the Data Flywheel on the Cloud
The video demonstrates deploying the data flywheel on the cloud using Launchable. The estimated cost is $12 per hour due to the use of a large GPU. The process involves:
- Clicking "Deploy to Cloud" on the provided link.
- Selecting "Deploy Launchable."
- Opening the notebook from the Launchable interface.
8. Notebook Walkthrough: AI Virtual Assistant
The notebook is designed for creating an AI virtual assistant for customer service, product Q&A, order status verification, returns processing, and small talk. The notebook includes four steps:
- Data Flywheel Setup
- Load Sample Data
- Create a Flywheel Job
- Monitor Job Status
9. Data Flywheel Setup (Step 1)
This step involves generating an API key and installing required Python packages (e.g., Elasticsearch, pandas, matplotlib). The video uses Llama 3 2 1B instruct model for fine-tuning. Nemo microservices, including the Llama 3 2 1B parameter model and a data store, are automatically started.
10. Loading Sample Data (Step 2)
The video uses a sample dataset containing question-and-answer pairs related to Nvidia products. The data is structured as a helpful support assistant for the Nvidia gear store. Users can replace this sample data with their own company information. The data is then loaded into Elasticsearch.
11. Creating and Monitoring a Flywheel Job (Steps 3 & 4)
The process triggers model training using the custom data. The job status is monitored, and the training process is compared against other models (e.g., Llama 3 1B, Llama 3 8B, Llama 3 70B) to evaluate accuracy and latency.
12. Evaluation and Results
The video highlights that the fine-tuned Llama 3 2 1B instruct model achieves accuracy comparable to the much larger Llama 3 70B instruct model while significantly reducing latency and compute usage.
13. Customization and API Endpoints
Users can customize API endpoints and publish them internally to trigger jobs with custom data and retrain the model with updated data.
14. Conclusion
The video concludes by emphasizing the effectiveness of the data flywheel approach and the benefits of using Nvidia Nemo microservices for creating AI agents. The fine-tuned Llama 3 2 1B instruct model offers a balance of accuracy and efficiency, making it suitable for AI customer service applications.
Main Takeaways:
- The data flywheel is essential for building scalable AI agents.
- Nvidia Nemo microservices provide a comprehensive toolkit for implementing the data flywheel.
- Fine-tuning smaller models with custom data can achieve comparable accuracy to larger models with reduced latency and compute costs.
- The provided notebook and cloud deployment options simplify the process of setting up and training AI models for specific use cases.
AI summaries can miss context or contain errors. Check important details against the original video.