Key Concepts
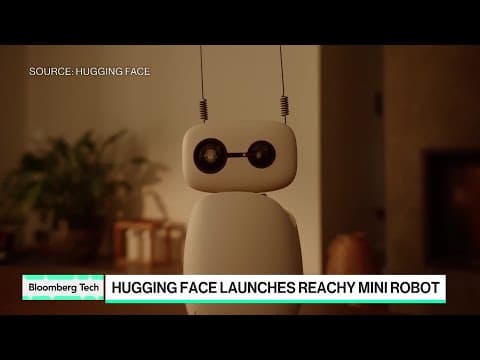
- Richie Mini: An affordable, open-source, hackable robot designed for researchers, students, and hobbyists.
- Voice AI Pipeline: A multi-stage system involving Voice Activity Detection (VAD), Speech-to-Text (STT), Large Language Models (LLMs), and Text-to-Speech (TTS).
- Streaming Inference: The process of generating audio/text in real-time chunks rather than waiting for the full output.
- Static KV Cache: A memory optimization technique for LLMs/TTS models that pre-allocates memory to avoid dynamic resizing, enabling faster inference.
- CUDA Graphs: A mechanism to capture and replay sequences of GPU operations, reducing CPU-GPU communication overhead.
- Real-Time Factor (RTF): A metric measuring the speed of generation; an RTF of 1.0 means 1 second of audio takes 1 second to generate.
1. The State of Robotics and the "Richie Mini" Philosophy
Andy Marafioti argues that current robotics development is overly focused on expensive, humanoid-mimicking hardware (often costing $50k+). He posits that this approach is a mistake because:
- Accessibility: High costs prevent students and researchers from prototyping.
- Design Constraints: Forcing robots to look human limits their potential for agility and creative utility.
- The "Hacker" Approach: Richie Mini is designed to be affordable ($300–$450), repairable, and modular. It is shipped unassembled to ensure users understand the hardware, fostering a community-driven, "hacker" culture rather than a corporate-controlled one.
2. Voice AI Architecture
The robot functions as a platform for voice interaction. The system architecture is divided into three levels:
- Client-Side (The Robot): Handles microphone input, speaker output, echo cancellation, and local hardware control (face tracking, motor movement).
- Speech-to-Speech Pipeline: Uses a VAD system to detect speech, a fast STT model (Parakeet) for transcription, an LLM for reasoning/tool calling, and a TTS engine for output.
- Infrastructural Backend: Deployed on Hugging Face inference endpoints with a load balancer. The LLM and TTS components are separated to optimize resource allocation based on concurrent user activity.
3. Optimizing Coqui TTS for Real-Time Performance
Marafioti detailed the technical challenges of making the Coqui 3 TTS model viable for voice agents. The original research implementation was too slow for interactive use. Key optimizations included:
- Streaming: Modifying the model to output audio packets as they are generated rather than waiting for the full sequence.
- Reducing CPU-GPU Overhead: The original model performed 500 steps per audio packet, requiring constant data transfer between CPU and GPU.
- Static KV Cache & CUDA Graphs: By switching to a static KV cache and using CUDA graphs, the team reduced the time-to-first-audio to under 200ms and improved the generation speed to 4x real-time (generating 1 second of audio in 250ms).
4. Practical Applications and Extensibility
- Customization: Users can 3D print parts, add sensors, or modify the robot’s physical appearance (e.g., turning it into a Halloween decoration).
- Interaction: The robot supports "vibe coding," where users can use LLMs to generate code for robot behaviors on the fly.
- Modularity: The Richie Mini is designed to be compatible with other open-source hardware projects like the SO100/SO101 robotic arms and the "Kiwi" mobile base.
5. Notable Quotes
- "If you take a humanoid robot, it could look like a spider and just move around way faster... but we're actually making it be a humanoid such that we look at it and we think, 'Oh, yeah, robot, human, it's the same.' That to me is a mistake."
- "We want the experience of the future to not be dominated by one company... but really it's made like computers were made in a bit more of a hacker fashion."
6. Synthesis and Conclusion
The Richie Mini project represents a shift from "product-focused" robotics to "platform-focused" robotics. By prioritizing affordability, open-source software, and real-time voice AI optimization, Marafioti aims to democratize robotics. The core takeaway is that the future of human-robot interaction lies in accessible, modular hardware paired with highly optimized, low-latency AI pipelines that allow users to define the robot's personality and utility through code and creative modification.
AI summaries can miss context or contain errors. Check important details against the original video.