THE SUMMARYAI-generated
Key Concepts
- RAG (Retrieval-Augmented Generation): An AI framework that combines a pre-trained language model with an information retrieval system to generate more accurate and context-aware responses.
- Vector Store: A database that stores data as high-dimensional vectors, enabling efficient similarity searches based on semantic meaning.
- Embedding Model: A machine learning model that converts text into numerical vectors (embeddings), capturing the semantic meaning of the text.
- Re-ranking: A technique used to improve the accuracy of RAG systems by reordering the results retrieved from a vector store based on their relevance to the user's query.
- Hybrid Search: A search strategy that combines vector search with traditional keyword-based search to improve retrieval recall and precision.
- Metadata Filtering: A technique that uses metadata associated with documents to filter the results retrieved from a vector store, improving the relevance of the results.
- Context Window: The maximum amount of text that a language model can process at once.
- Context Stuffing: The practice of providing more and more information into prompts.
- By-encoder Models: Embedding models where the document chunk and the query are embedded in complete isolation.
- Cross-encoder Models: Re-ranker models where the document chunk and the query are sent into the transformer model at the same time.
Vector Search and its Limitations
- Process: Documents are chunked into segments, transformed into numerical vectors using an embedding model, and stored in a vector database.
- Querying: A user's question is also converted into a vector, and the vector database is searched for the closest matching document vectors.
- Information Loss: Compressing the meaning of text into a single vector point leads to information loss, resulting in potentially irrelevant results being returned.
- Context Stuffing Problem: Increasing the number of results from the vector store (context stuffing) can degrade the LLM's performance due to limitations in its context window and the "lost in the middle" problem.
Re-ranking: A Solution to Information Loss
- Maximizing Recall: Re-ranking maximizes retrieval recall by increasing the number of results coming from the vector store.
- Maximizing LLM Recall: Re-ranking maximizes LLM recall by preventing the LLM's context from being polluted with irrelevant chunks.
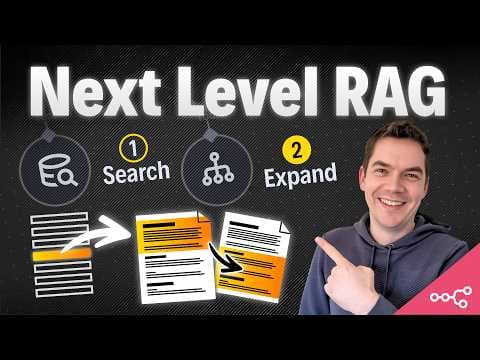
- Two-Stage Retrieval: Re-ranking is a two-stage retrieval process:
- Stage 1: A vector store quickly retrieves a larger set of potentially relevant results (e.g., 25 out of tens of thousands).
- Stage 2: A re-ranker model analyzes the retrieved results and selects the top most relevant ones (e.g., top 3).
- Accuracy Advantage: Re-rankers are more accurate than embedding models because they use cross-encoder models, which consider the query and document chunk simultaneously.
Coher's Re-ranking Models
- Industry Standard: Coher's ranking models are a de facto standard and can be deployed on various cloud platforms or accessed via their API.
- Accuracy Improvement: Benchmarks demonstrate that adding re-ranking to an AI agent significantly improves the accuracy of results.
N8N Implementation of Coher's Re-ranker
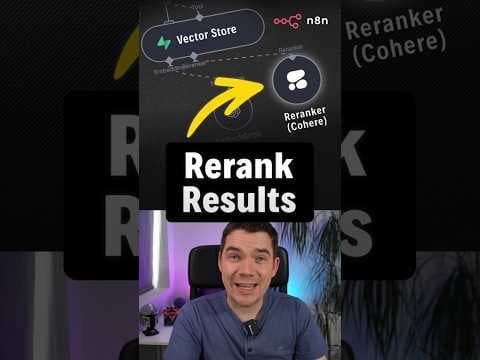
- New Feature: N8N version 1.98 and higher includes a re-rank results toggle in the vector store node, allowing connection to a re-ranker.
- Coher's Integration: Currently, only Coher's re-ranker is supported via a dedicated node.
- Configuration: Requires a Coher API key and selection of the re-rank model (e.g., 3.5).
- Metadata Handling: The N8N implementation automatically sends metadata associated with the chunks to the Coher re-ranker.
- Limitation: The number of results returned by the Coher re-ranker is hardcoded to three, limiting flexibility in maximizing retrieval recall.
- Feature Request: A feature request has been submitted to N8N to allow overriding the number of results returned by the re-ranker and to enable/disable the passing of metadata.
Advanced Techniques: Hybrid Search and Metadata Filtering
- Subworkflow Approach: Instead of using the vector store node directly, a subworkflow is triggered to implement more complex logic.
- Metadata Filtering: Metadata filters are used to create subsets of vectors based on specific criteria (e.g., motorsport category, year).
- Hybrid Search Implementation: Hybrid search is implemented in Superbase, combining full-text search with vector search.
- HTTP Request Node: An HTTP request node is used to trigger the Coher re-ranker with the results from the hybrid search.
Conclusion
Re-ranking is a powerful technique for improving the accuracy of RAG systems by addressing the information loss inherent in vector search. While N8N's current implementation has limitations, it provides a basic framework for integrating Coher's re-ranker. Combining re-ranking with other advanced techniques like hybrid search and metadata filtering can further enhance the performance of AI agents.
AI summaries can miss context or contain errors. Check important details against the original video.