THE SUMMARYAI-generated
Key Concepts:
- AI Scraping Bots: Automated programs that extract data from websites to train AI models.
- Robots.txt: A text file in a website's root directory that provides instructions to web robots about which parts of the site should not be processed or scanned.
- RFC 9309: A standard way to control data access for automated bots using directives like user-agent and disallow.
- Disallow AI Training: A proposed directive for robots.txt to prohibit data access for AI training purposes.
- Allow AI Training: A proposed directive for robots.txt to permit data fetching for AI training purposes.
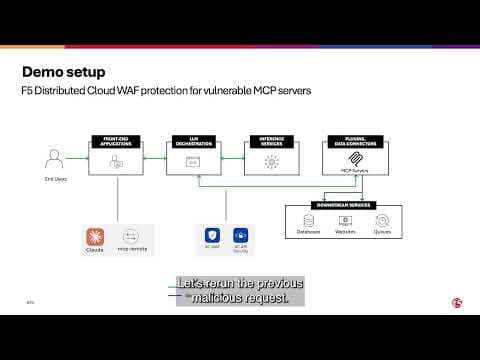
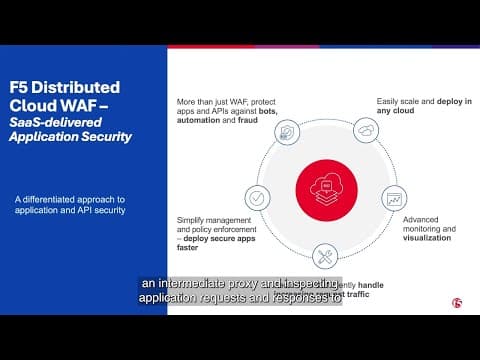
- F5 Distributed Cloud WAAP (F5XC WAAP): F5's web application and API protection platform.
- Direct Response Route: A configuration in F5XC that specifies the response F5XC will send back to the client.
- Scrapy: A Python library for web scraping.
- User-Agent Header: An HTTP header that identifies the client software originating the request.
- Client Blocking Rule: A rule in F5XC that blocks requests based on client characteristics, such as user-agent.
- Service Policy: A policy in F5XC that defines rules for handling traffic based on various criteria, including TLS fingerprint and user-agent.
- TLS Fingerprint: A unique identifier for a TLS connection, based on the cryptographic parameters used.
1. Robots.txt Directives for AI Scraping Control
- Main Point: The video addresses the growing concern of AI scraping and introduces methods to control data access for AI crawlers using robots.txt directives.
- Details:
- Traditional web scraping is exacerbated by AI's need for training data.
- RFC 9309 provides standard directives (user-agent, disallow) for bot control.
- Proposed directives:
Disallow AI Training: Prevents data access for AI training.Allow AI Training: Permits data fetching for AI training.
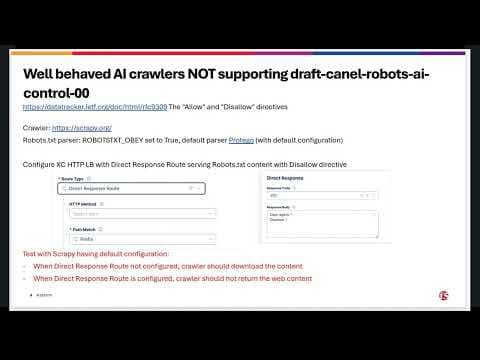
- Example: The video uses the Scrapy library to simulate a web crawler.
- Process:
- Create a direct response route in F5XC to serve a custom robots.txt file.
- Include
Disallow AI TrainingorAllow AI Trainingdirectives in the robots.txt content. - Configure the Scrapy crawler to obey robots.txt rules.
- Observe that the crawler is either blocked or allowed based on the robots.txt directives.
2. Mitigation Using User-Agent Blocking
- Main Point: Blocking specific scraping tools based on their user-agent header.
- Details:
- If bots ignore robots.txt, blocking by user-agent is an alternative.
- Process:
- Identify the user-agent of the scraping tool.
- Configure a client blocking rule in F5XC to block requests with that specific user-agent.
- Verify that requests from the scraping tool are blocked.
- Example: The video demonstrates blocking a Scrapy crawler by setting a specific user-agent and creating a corresponding blocking rule in F5XC.
- F5XC Security Logs: Confirms the request is blocked because of the client blocking rule.
3. Blocking Suspicious Bot Categories
- Main Point: Blocking entire categories of bots identified as suspicious.
- Details:
- Instead of blocking individual tools, block entire bot categories.
- Process:
- Configure F5XC WAAP to block all suspicious bots.
- Run the scraping script.
- Verify that the request is blocked by F5XC WAAP.
- F5XC Security Logs: Shows the request is blocked because it was identified as coming from a suspicious bot.
4. Service Policy with TLS Fingerprint and User-Agent
- Main Point: Using a combination of TLS fingerprint and user-agent to block bots that masquerade as legitimate clients.
- Details:
- Bots may try to bypass user-agent blocking by spoofing their user-agent.
- TLS fingerprint provides a more reliable way to identify bots.
- Process:
- Inspect F5XC security logs to identify the TLS fingerprint of the bot.
- Create a service policy in F5XC with two rules:
- Rule 1: Block requests matching the specific TLS fingerprint (and optionally, user-agent, path, etc.).
- Rule 2: Allow all other requests.
- Verify that requests from the bot are blocked.
- Example: The video demonstrates blocking a bot by its TLS fingerprint, even if it attempts to use a legitimate user-agent.
- Event Logs: Confirms the request is blocked because of the service policy.
5. Conclusion
- Main Takeaway: F5 Distributed Cloud WAAP offers multiple methods to mitigate AI scraping bots, including robots.txt directives, user-agent blocking, bot category blocking, and service policies based on TLS fingerprint and user-agent. These methods provide a layered approach to protect web applications from unwanted AI scraping.
AI summaries can miss context or contain errors. Check important details against the original video.