THE SUMMARYAI-generated
Key Concepts
- RL Kernels, Agents, and Quantization: Core topics of the presentation.
- Llama: Foundation of open-source LLMs.
- Open Source Drought: Period of stagnation in open-source LLM capabilities.
- SFT/RHF Jump: Performance increase from supervised fine-tuning and reinforcement learning from human feedback.
- RLVR (Reinforcement Learning with Verifiable Rewards): New paradigm using reward functions to improve models.
- Agents: Language models interacting with an environment to maximize rewards.
- RHF (Reinforcement Learning from Human Feedback): Training models based on human preferences.
- PO (Proximal Policy Optimization): Optimization algorithm for RHF.
- GRPO (Generalized Relative Policy Optimization): Variant of PO without a value model.
- Quantization: Reducing model size and memory usage.
- Dynamic Quantization: Selective quantization of layers.
- Torch.compile: PyTorch tool for optimizing model performance.
History and Evolution of Large Language Models
- Llama's Impact: The leaked Llama model spurred the open-source LLM movement.
- Training Data and Model Size: Llama 1 was trained on 1.4 trillion tokens, while newer models like Gemma and Llama 4 are trained on 10-30 trillion tokens. Larger models generally have lower training loss.
- Open Source vs. Closed Source: Open-source models have caught up to closed-source models in terms of MLU, but there was an "open-source drought" after the release of 01 preview. Deepseek R1 helped bridge the gap.
- The SFT/RHF Jump: Supervised fine-tuning (SFT) and reinforcement learning from human feedback (RHF) significantly improve model performance.
- Yan Lakun's Cake Analogy: Pre-training is the cake, SFT is the icing, and reinforcement learning is the cherry.
Training Stages and Methodologies
- Base Model to Chat Model: Converting a base model to a chat model involves fine-tuning.
- Pre-training, Mid-training, SFT, Post-training, RLVR: Stages of model training, with mid-training focusing on higher quality data and long context extension.
- Optimization Problem: Training LLMs is an optimization problem of moving from a random initialization to the final model state.
- Bypassing SFT and Preference Fine-tuning: Deepseek Zero showed that it's possible to skip SFT and preference fine-tuning and directly use RLVR.
Agents and Reinforcement Learning
- Agent-Environment Interaction: An agent (language model) interacts with an environment, takes actions, and receives rewards.
- RL Loop in Language Models: The RL loop is modified because the state doesn't change over time as it does in games.
- Reward Function Design: Designing reward functions involves assigning values to different actions or outputs. Distance-based scoring can be used for mathematical problems.
- RHF Process: Interacting with the agent, getting actions, feeding them into a reward model, and iteratively improving the model.
- PO and GRPO: PO is an optimization algorithm for RHF. GRPO removes the value model for efficiency.
Reinforce Algorithm and Advantage
- Maximizing the Equation: The goal of RL is to maximize the equation: gradient with respect to the policy language model of the log probability of the action given the state times the reward.
- Advantage: The advantage is the reward minus the average reward (baseline). The goal is to maximize the advantage, not just the reward.
- Value Model: The value model estimates the average reward given the current state. GRPO deletes the value model.
PO and Overfitting
- PO Formula: The PO formula includes the probability of the action given the state times the advantage, along with terms to reduce overfitting.
- Likelihood Ratio: PO maximizes the likelihood ratio to avoid reward hacking.
- Trust Region (Epsilon): The epsilon part of PO constrains the model to prevent large steps and overfitting.
- KL Divergence: The KL divergence term in PO keeps the model close to the supervised fine-tuned model.
GRPO and Rollouts
- GRPO's Approach: GRPO removes the value model and the reward model.
- Rollouts and Statistics: GRPO uses rollouts (inference sampling) to generate multiple outputs and then takes the statistics (mean, standard deviation) to calculate the z-score.
- Group Relative: GRPO takes the statistics within each group of questions.
Quantization Techniques
- Dynamic Quantization: Quantizing mixture of expert layers heavily while leaving attention layers and shared experts in higher precision.
- Activation and Weight Quantization Error: Checking these errors helps determine which layers should not be quantized.
- Super Weights Paper: This paper discusses the importance of certain weights in language models and why they should not be quantized.
- Numerical Precision and GPU Speed: GPUs are getting faster due to numerical precision (float 32 to float 16 to float 8 to float 4). Float 4 may be the final precision level.
Torch.compile
- Torch.compile Benefits: Torch.compile can make training faster and reduce memory usage.
- Torch.compile Options: There are many options that can be tuned for torch.compile.
Colab Demonstration (Quen 3 GPO)
- VLM and Unsoft: The demonstration uses VLM for serving the model and unsoft for fine-tuning.
- Laura: Laura is used for parameter-efficient fine-tuning.
- System Prompt: The system prompt is used to guide the model's reasoning process.
- Chat Template: A chat template is needed for base models to understand how to do conversations.
- Supervised Fine-tuning (Priming): Supervised fine-tuning is used to prime the model before RL.
- Reward Function Creation: Creating reward functions is the most important part of the process.
- Regular Expressions: Regular expressions are used to match the format of the model's output.
- Distance-Based Scoring: Distance-based scoring is used to reward answers that are close to the correct answer.
- Training Loop: The training loop involves calling VLM, calculating the reward, and updating the model.
- Training Metrics: The training metrics include reward, completion length, and KR divergence.
Conclusion
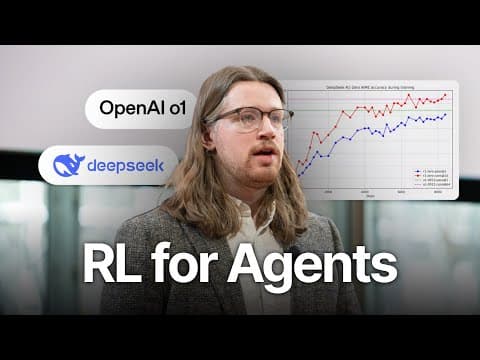
The presentation provides a deep dive into RL kernels, agents, and quantization. It covers the history and evolution of LLMs, training methodologies, RL techniques, and quantization strategies. The Colab demonstration showcases how to use unsoft and VLM to fine-tune a model using GRPO. The key takeaways are the importance of reward function design, the benefits of GRPO, and the potential of quantization to reduce model size and memory usage. The presentation also emphasizes the importance of efficiency and experimentation in the field of AI.
AI summaries can miss context or contain errors. Check important details against the original video.