Key Concepts
- VLM AI Inference: Utilizing Large Language Models (LLMs) for AI inference, characterized by slow, non-uniform, and computationally/economically expensive requests.
- Intelligent Load Balancing: A two-stage approach to load balancing LLM requests, incorporating business logic (body-based routing) and real-time server metrics.
- Body-Based Routing: Routing requests based on the content of the request body (specifically, JSON data).
- Prometheus Telemetry: A system for collecting and monitoring metrics from OpenShift, crucial for dynamic load balancing.
- LLM Load Controller: A component that processes VLM metrics and provides load ratios to the load balancer.
- KV Cache Utilization: A metric indicating the efficiency of key-value cache usage within the LLM servers, impacting performance.
- F5 BIG-IP: The load balancing solution used in the demonstration.
- OpenShift: The container orchestration platform hosting the VLM AI inference model servers.
Characteristics of AI Inference Workloads & the Need for Intelligent Load Balancing
The demonstration focuses on the unique challenges of load balancing requests to VLM AI inference model servers. Unlike traditional HTTP workloads which are fast, uniform, and inexpensive, LLM requests are slow, non-uniform, and significantly more expensive due to GPU usage. This disparity justifies investing in CPU resources for precise load balancing to maximize GPU efficiency. The variability in LLM request computational demands – influenced by prompt length, model differences, and prior outputs – leads to unpredictable request processing times. Traditional load balancing methods are insufficient for this scenario.
Intelligent Load Balancing: A Two-Stage Process
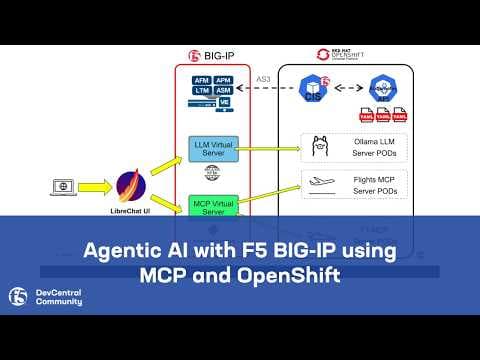
F5 BIG-IP facilitates intelligent load balancing through a two-stage process. First, business logic is applied to the incoming request. In this demonstration, this takes the form of body-based routing. Second, within the selected pool, BIG-IP selects the most appropriate LLM server based on real-time metrics gathered from the servers themselves. These metrics are sourced from OpenShift’s integrated Prometheus telemetry.
Body-Based Routing Implementation
The business logic implemented is body-based routing, achieved by parsing the JSON request body. BIG-IP’s native JSON support is leveraged to evaluate specific elements within the JSON object, such as the requested model, whether the request originates from an interactive application, and the requested role for the AI model. Instead of traditional iRule programming, the configuration is managed through a data group. Each step in the business logic diagram is assigned an ID, along with the JSON element to check, the comparison value, and the next step based on whether the condition is met. This approach allows for rapid adaptation to changing business requirements without requiring iRule expertise. The demonstration showcases this by routing three distinct batches of 10 AI requests to different LLM pools based on their content and the defined business logic.
Dynamic Load Balancing Based on Server Metrics
The second stage focuses on optimizing the VLM servers within the pool selected during body-based routing. Traditional load balancing struggles with LLM workloads because of slow and non-uniform response times, making it difficult to accurately assess server load. Effective load balancing requires gathering VLM-specific metrics, including request queue depth, request processing time, and KV cache utilization. The KV cache, a key-value store, significantly impacts LLM performance; its utilization rate is a critical metric.
OpenShift, utilizing Prometheus and Thanos telemetry, collects these metrics. An LLM load controller then processes these metrics and generates a load ratio for each server. This ratio indicates the server’s capacity and is fed back to BIG-IP. BIG-IP uses this dynamically updated ratio (updated every few seconds) to bias its load balancing decisions, improving response times and optimizing hardware utilization.
Demonstration of Dynamic Load Balancing in Action
The demonstration illustrates this process by initially sending requests to a model using round-robin load balancing. This results in an imbalanced load as some VLM servers become busier than others, even with equal request distribution. When dynamic load balancing is enabled, leveraging the metrics from the VLM servers, the load is redistributed, returning to a more even distribution. This is particularly evident during traffic spikes, where the system continuously readjusts the load ratios to maintain optimal performance.
Technical Terms Explained
- Prometheus: An open-source systems monitoring and alerting toolkit.
- Thanos: An open-source, highly-available, and scalable Prometheus-compatible monitoring system.
- KV Cache: A key-value cache used to store frequently accessed data, improving LLM performance.
- iRules: F5’s proprietary scripting language for customizing BIG-IP behavior.
- Telemetry: The automated collection of data about a system’s state and performance.
Logical Connections
The demonstration logically progresses from identifying the challenges of LLM workload balancing to presenting a solution based on a two-stage intelligent load balancing approach. Body-based routing provides initial request categorization, while dynamic load balancing based on server metrics optimizes resource utilization within each category. The integration of OpenShift’s Prometheus telemetry is central to the success of the dynamic load balancing stage.
Conclusion
This demonstration highlights the necessity of intelligent load balancing for VLM AI inference model servers. By combining body-based routing with dynamic load balancing driven by real-time server metrics, it’s possible to significantly improve performance, optimize hardware utilization, and adapt quickly to evolving business requirements – all without requiring complex iRule programming. The integration of F5 BIG-IP with Red Hat OpenShift and its Prometheus telemetry provides a powerful and automated solution for managing these demanding workloads. Further details on the implementation can be found in the associated article.
AI summaries can miss context or contain errors. Check important details against the original video.